On Information
I’ve wondered about entropy for a long time. From thermodynamics and the arrow of time, to cross-entropy loss in ML cost functions, or KL divergence in stopping intelligence from going batshit crazy in VAE/PPO, entropy keeps cropping up. Maybe the universe is playing some kinda trick on us here. Since I’m taking 3F7 Information Theory, I thought it’s probably a good time to understand what these ideas really mean.
Disclaimer: I do not claim this work to be my own; this is merely a synthesis of intuition and math across multiple resources for myself and anyone interested. In particular, we borrow the beautiful figures and analogies from Chris Olah’s amazing post1 on Information Theory.
Contents
1 Entropy and Self-Information
We introduce entropy as the fundamental limit to compressing information.
1.1 Optimal Encoding
Encoding
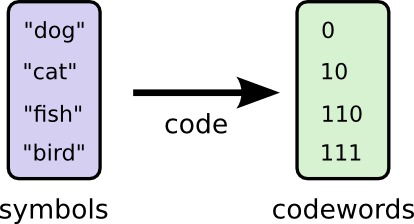
Suppose my friend Jerry is at the London Zoo, while I’m (Zach) at the Singapore Zoo. There’s only 4 kinds of animals in both zoos: “dog”, “cat”, “fish” and “bird”. Today, he’s telling me which animals he saw at the London Zoo - but for whatever reason he can only communicate in binary (0s and 1s).
To communicate, Jerry and I have a secret code mapping animals to sequences of bits. We use a simple mapping, which uses 2 bits to encode 4 animals/symbols:
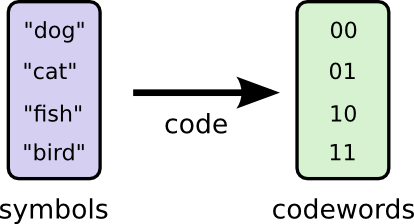
Technically, the animals are symbols $x_i$, with their collective called an alphabet $\{x_1 \dots x_i \dots x_n\}$. Their respective binary representations are called “codewords” and the original string message is “encoded” into its binary representation.
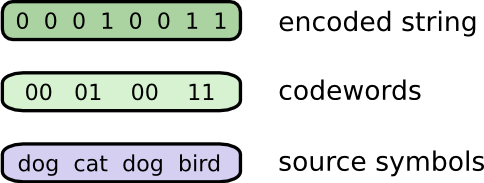
Variable Encoding
All animals are equal, but some animals are more equal than others.
There are different numbers for each animal type in the London Zoo. We can plot a diagram showing the probability distribution of the animals and the length of our codeword representations:
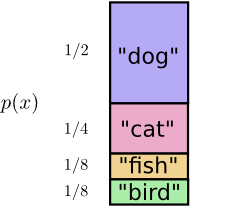
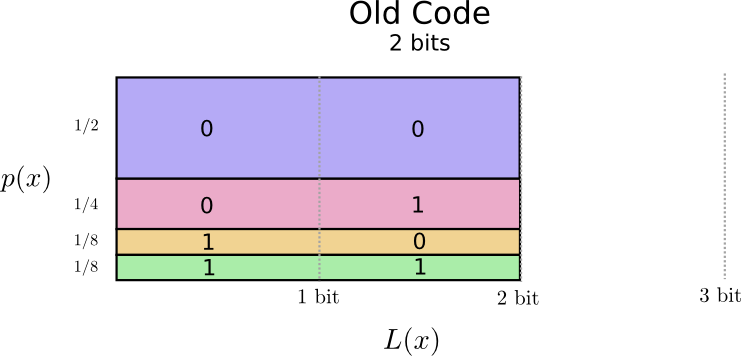
The vertical axis shows the probability $p(x_i)$ of each animal seen by Jerry, while the horizontal axis shows the length of the corresponding codeword $L(x_i)$ in our secret code mapping. Notice the total area summed over all codewords $\sum_{i} p(x_i) L(x_i)$ is in fact the average length $\mathbb{E}[L(X)]$ of codewords in our mapping!
Information is expensive - we’d like to minimize this average length $\mathbb{E}[L(X)]$. Let’s exploit this uneven-ness in the probability distribution, and assign shorter codewords to more frequent animals:
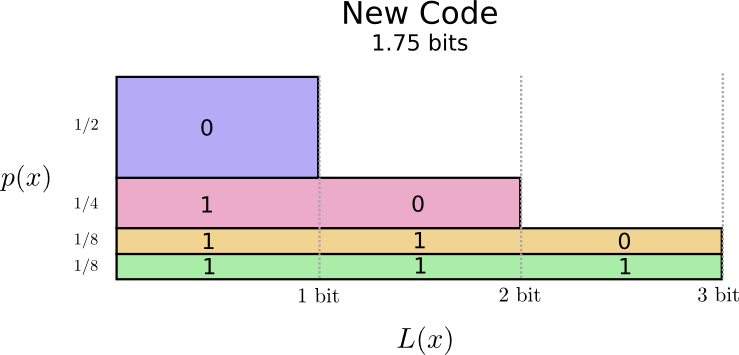
The average length of codewords (total area above) went down from 2 bits to 1.75 bits! How much further can we reduce this? Turns out there’s a fundamental limit - we call this the entropy of the probability distribution. To understand why such a limit exists and how to compute it, we need to understand the tradeoffs between making some codewords short and others long.
Tradeoffs in the Space of Codewords, Kraft’s Inequality
To understand this tradeoff, we visualize all possible codewords first on a table and then on a tree:
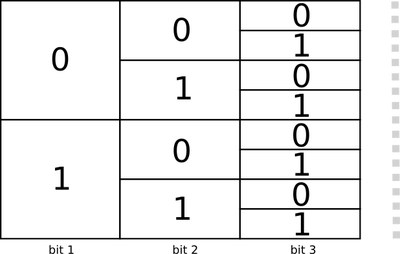
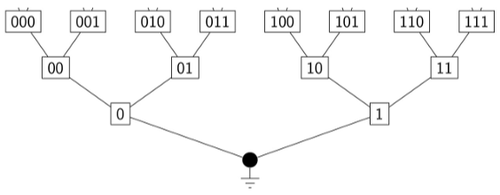
We need our code to be uniquely decodable, which means that given an encoded string there is only one way to decode it back to our animal symbols. (e.g. an alphabet $\{0, 1, 01\}$ as codewords is not uniquely decodable because 001 could mean $[0,0,1]$ or $[0,01]$) One way to achieve this property is to create a prefix-free code, which means no codeword can be the prefix of another codeword. In terms of trees, this means every codeword must be a leaf node. By enforcing this prefix-tree condition, we have to make tradeoffs whenever we use a codeword. Consider using $01$ as a codeword:
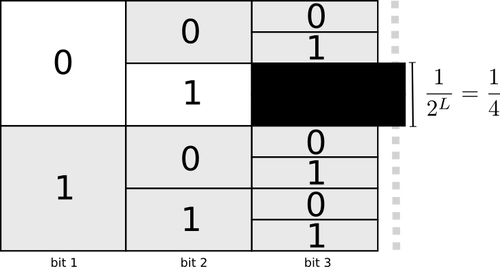
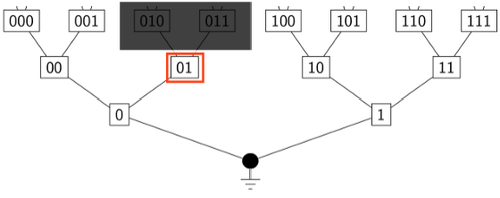
A quarter of codewords $\{010, 011\}$ (assuming we only used 3bit codewords) would be gone from the space of codewords. We see that a shorter codeword requires you to sacrifice more of the space of possible codewords. In fact we can quantify this tradeoff as Kraft’s inequality:
Consider a full binary tree of depth $L_{max}$, which has $2^{L_{max}}$ leaves. Whenever we use a codeword $x_i$ at depth $L(x_i)$, we eliminate all its descendant leaves - that’s $2^{L_{max} - L(x_i)}$ leaves becoming unavailable. For a prefix-free code with codewords at depths $L_1, L_2, \ldots, L_n$, the total number of unusable leaves is:
$$\sum_{i=1}^{n} 2^{L_{max} - L(x_i)}$$This sum cannot exceed the total number of leaves $2^{L_{max}}$:
$$\sum_{i=1}^{n} 2^{L_{max} - L(x_i)} \leq 2^{L_{max}}$$Dividing both sides by $2^{L_{max}}$:
$$\sum_{i=1}^{n} 2^{-L(x_i)} \leq 1$$This is Kraft’s inequality. It’s both a necessary condition (any prefix-free code must satisfy it) and a sufficient condition (if a set of lengths satisfies it, we can construct a prefix-free code with those lengths). This inequality formalizes the tradeoff in the space of codewords - shorter codewords are “expensive” as they eliminate more possibilities. Assuming a total space of $1$, each codeword $x_i$ of length $L(x_i)$ costs $2^{-L(x_i)}$ of the total space of codewords. We can think of the total space as a maximum fixed “budget” of $1$, and each codeword costing $2^{-L(x_i)}$ of this budget.
Optimal Encodings
We’ve showed the cost of codewords decreases exponentially with its length. We can visualize this 2 with the cost on the vertical axis and the length on the horizontal axis of an exponential curve:
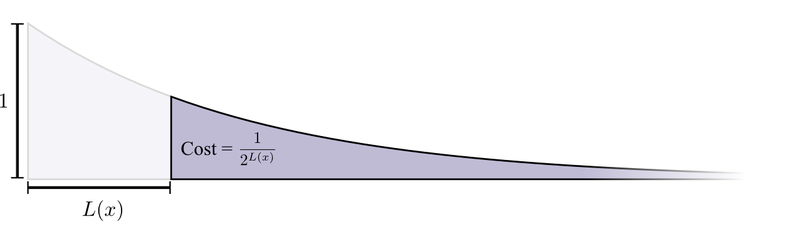
Note that since cost decays exponentially, the height and the right shaded area are numerically equal when using natural exponentials2. We can also visualize the contribution $p(x_i) L(x_i)$ of this codeword to the average codeword length:
$$\mathbb{E}[L(X)]=\sum_{i} p(x_i) L(x_i)$$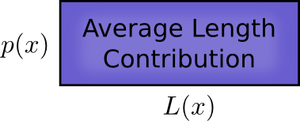
Visualizing both the cost and length contribution we get:
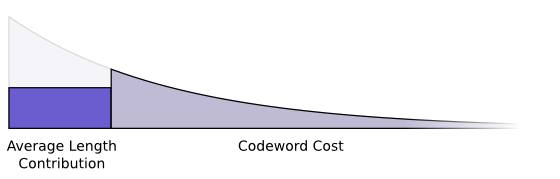
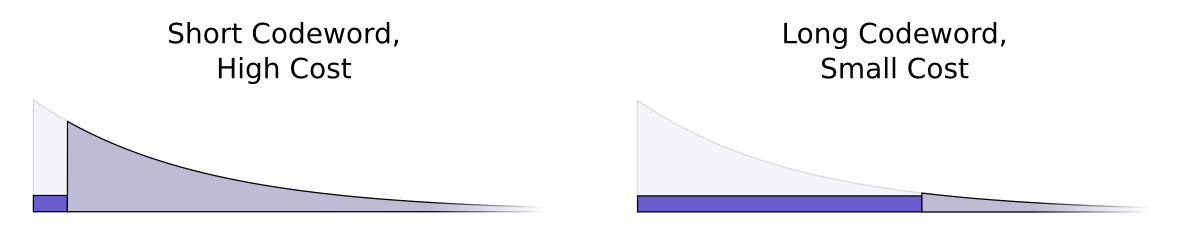
The above diagram makes the tradeoff clear: short codewords reduce the average message length but are expensive, while long codewords increase the average message length but are cheap. So what’s the optimal allocation of the codeword space budget to each symbol $x_i$, so that the average codeword length is minimized? We propose that if a symbol (or event) $x_i$ appears with probability $p(x_i)$, then the optimal allocation is to allocate $p(x_i)$ of the codeword space budget to this symbol. Here’s a handwavy proof:3
$$ \text{Cost}(x_i)=2^{-L(x_i)}=p(x_i), \forall i $$$$ \frac{d\big(\text{Length Contribution}(x_i)\big)}{dL(x_i)} = \frac{d\big(p(x_i) L(x_i)\big)}{dL(x_i)} = p(x_i) $$$$ \frac{d\big(\text{Cost}(x_i)\big)}{dL(x_i)} = \frac{d\big(2^{-L(x_i)}\big)}{dL(x_i)} = -2^{-L(x_i)} \ln(2) $$At the optimal allocation where $2^{-L(x_i)} = p(x_i)$,
$$\frac{|d(\text{Length Contribution})/dL|}{|d(\text{Cost})/dL|} = \frac{\text{Marginal benefit from shorter codeword}}{\text{Marginal cost in codeword space}} = \frac{p(x_i)}{2^{-L(x_i)}\ln(2)} = \frac{1}{\ln(2)}$$which is constant regardless of $p(x_i)$. This means at the optimal budget, it’s equally worthwhile to invest in making any codeword shorter as all codewords have the same marginal benefit/cost ratio. Note that the actual value of this ratio doesn’t matter (the top and bottom quantities don’t have the same units so we cannot compare them meaningfully in terms of absolute values) - what matters is the relative ratios between the different symbols.
If $2^{-L(x_i)} \ne p(x_i)$, then this would mean the ratio for each ${x_i}$ would in fact be dependent on both $L(x_i)$ and $p(x_i)$, and will result in uneven - hence suboptimal allocation of budgets. Any uneven-ness of this ratio means it will make more sense to spend more budget in one codeword than other codewords.
Calculating Entropy
Since the cost of an encoded message of length $L(x_i)$ is $2^{-L(x_i)}$, then $L(x_i)=\log_2\left(\frac{1}{\text{Cost}}\right)$. Since for optimum allocation of budgets (to minimize average lengths), we allocated $p(x_i)$ of the budget to $L(x_i)$, then
$$L(x_i)=\log_2\left(\frac{1}{p(x_i)}\right)$$The average message length under optimal allocation is
$$\mathbb{E}[L(X)] = \sum_{i} p(x_i) L(x_i) = \sum_{i} p(x_i) \log_2\left(\frac{1}{p(x_i)}\right) $$Kraft’s inequality created a budget constraint on how many short codewords you can have. The optimal strategy is to spend this budget proportionally to symbol probabilities. Any other allocation either violates the constraint (making the code invalid, like not prefix-free) or wastes budget (making the average length longer). Hence for a probability distribution of symbols, the minimum average length across all the encoded symbols is:
$$\min_{\text{all encodings}} \mathbb{E}[L(X)] = \sum_{i} p(x_i) \log_2\left(\frac{1}{p(x_i)}\right)$$Note that
$$H(X) = \sum_{i} p(x_i) \log_2\left(\frac{1}{p(x_i)}\right)$$hence
$$H(X) = \min_{\text{all encodings}} \mathbb{E}[L(X)]$$Entropy emerges because it’s the only allocation that balances the budget constraint with minimizing average length! The more concentrated the probability, the easier it is to exploit this by crafting short encodings. The more spread out the probability, the less I am able to exploit this, and I have to make all my encodings longer on average. So a distribution with higher uncertainty requires more bits to communicate information.
1.2 Source Coding Theorem
We’ve shown the intuition that the optimal codeword allocation follows $2^{-L(x_i)} = p(x_i)$, yielding entropy. Here’s the actual proof for this - Shannon’s source coding theorem. We’ve seen that prefix-free codes obeys the budget constraint $\sum_{i} 2^{-L(x_i)} \leq 1$, and McMillan4 proved the same constraint holds for all uniquely decodable codes (of which prefix-free codes are just a subset). Consider a general (possibly non-optimal) coding scheme giving length $L(x_i)$ for symbol $x_i$:
$$H(X) - \mathbb{E}[L(X)] = \sum_{i} p(x_i) \log_2\left(\frac{1}{p(x_i)}\right) - \sum_{i} p(x_i) L(x_i)$$$$= \sum_{i} p(x_i) \log_2\left(\frac{2^{-L(x_i)}}{p(x_i)}\right)$$$$= \frac{1}{\ln 2} \sum_{i} p(x_i) \ln\left(\frac{2^{-L(x_i)}}{p(x_i)}\right)$$Note for any $x > 0$, we have $\ln(x) \leq x - 1$ (with equality only when $x = 1$). This gives us:
$$H(X) - \mathbb{E}[L(X)] \leq \frac{1}{\ln 2} \sum_{i} p(x_i) \left(\frac{2^{-L(x_i)}}{p(x_i)} - 1\right)$$$$\frac{1}{\ln 2} \left(\sum_{i} 2^{-L(x_i)} - 1\right) \leq 0$$where we’ve used McMillan’s constraint $\sum_i 2^{-L(x_i)} \leq 1$. Therefore
$$H(X) \leq \mathbb{E}[L(X)]$$no encoding can beat entropy.
Shannon’s Source Coding Theorem
For any uniquely decodable code encoding symbols (where $L(X)$ gives the length of the codeword for symbol $X$) from a distribution with entropy $H(X)$:
$$H(X) \leq \mathbb{E}[L(X)]$$This limit explains why:
- Random data doesn’t compress — it has maximum entropy because all symbols are equally likely, we can’t exploit shorter messages for more common events
- English text compresses well — it has entropy $\sim 1.5$ bits per letter (much less than uniform distribution $\log_2(26) \approx 4.7$) because letter probabilities are wildly uneven
2 Cross-Entropy
Turns out the distribution of animals is different in the London Zoo $P$ and Singapore Zoo $Q$:
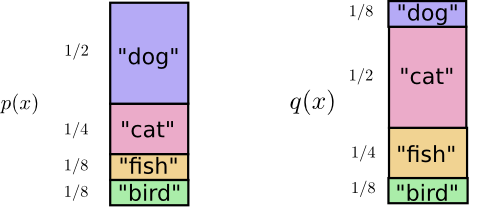
What if I design my code mapping to be locally optimal for the Singapore Zoo, but Jerry is actually sending me data from the London Zoo overseas? That is, I optimize codeword lengths $L(x_i) = \log_2\left(\frac{1}{q(x_i)}\right)$ for distribution $Q$ (Singapore), but the actual data comes from distribution $P$ (London). The expected codeword length becomes:
$$H_P(Q) = \sum_i p(x_i) \log_2\left(\frac{1}{q(x_i)}\right)$$We call this the cross-entropy from $P$ to $Q$. It represents the average length of encoded messages for data actually drawn from distribution $P$, using an optimal code designed for distribution $Q$. Since we have used the unoptimized code mapping on distribution $P$, we have to pay a cost through an increase in the average length of encoded messages $H_P(Q) \geq H(P)$:
$$H_P(Q) = H(P) + D_{KL}(P \| Q)$$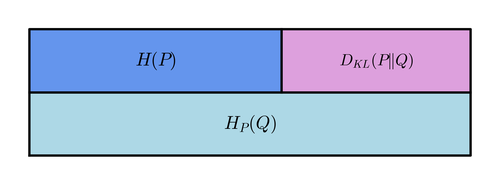
- $H(P)$: The irreducible minimum—the entropy of the true underlying distribution
- $D_{KL}(P \| Q)$: The penalty for mismatch—how much extra bits we waste by optimizing for the wrong distribution
This mismatch means we waste bits on unexpected events (where $p(x_i) > q(x_i)$) while potentially using longer-than-necessary codes for common events (where $p(x_i) < q(x_i)$), hence giving a length penalty. When $Q = P$ (our assumption is perfect), the second term vanishes and cross-entropy equals entropy—we’re encoding optimally. When they differ, $D_{KL}(P \| Q) > 0$ quantifies exactly the penalty. In this sense, cross-entropy gives us a measure of how different 2 probability distributions are. The more different 2 distributions are, the bigger the cross-entropy $H_P(Q)$.
Asymmetry
Cross-entropy is fundamentally asymmetric $H_P{(Q)} \ne H_Q{(P)}$:
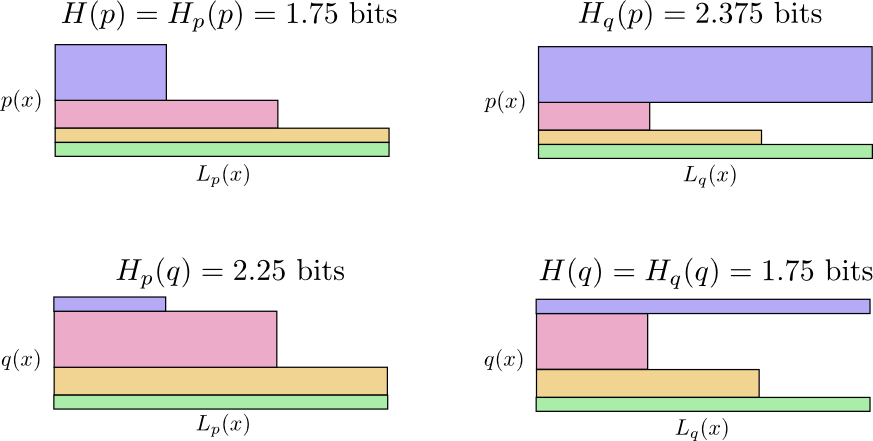
$H_P{(Q)}$ is large because we pay a very large penalty using a long codeword (that’s rare in $Q$ but common in $P$) for the purple symbol. On the other hand, this extra cost for using unnecessarily longer codewords when encoding real data from $Q$ is not quite as big.
3 KL Divergence
Now that we understand cross-entropy, we can isolate the pure cost of mismatch. The Kullback-Leibler (KL) divergence is exactly this: cross-entropy minus the intrinsic entropy.
$$D_{KL}(P \| Q) = H_P(Q) - H(P) = \sum_i p(x_i) \log\left(\frac{p(x_i)}{q(x_i)}\right)$$This is the extra bits we pay because we optimized for the wrong distribution $Q$ instead of the the distribution where samples came from $P$. Note the the following properties:
- Non-negativity: $D_{KL}(P \| Q) \geq 0 \text{, with equality iff } P = Q$
- Not really a metric 5 6
- Asymmetry $D_{KL}(P \| Q) \neq D_{KL}(Q \| P)$ 7
- Forward KL: $D_{KL}(P \| Q)$ (what we usually minimize) is mean-seeking. If $P$ is bimodal, and we optimize $Q$ to reduce KL, then $Q$ diffuses to cover both modes
- Reverse KL: $D_{KL}(Q \| P)$ is mode-seeking. To minimize KL, $Q$ collapses onto a single mode of $P$ rather than spreading across both
4 Mutual Information
Mutual information measures how much one variable reduces the uncertainty about another:
$$I(X; Y) = D_{KL}(P(X,Y) \| P(X)P(Y))$$This compares the joint distribution $P(X,Y)$ against what we’d expect if $X$ and $Y$ were independent: $P(X)P(Y)$. When variables are independent, the joint factorizes and the KL divergence is zero—they share no information. When they’re dependent, $I(X; Y) > 0$ quantifies the dependence. Using the decomposition $H_P(Q) = H(P) + D_{KL}(P \| Q)$, we can also expand:
$$I(X; Y) = H(X) - H(X|Y)$$This form says: “mutual information is the reduction in uncertainty about $X$ when we learn $Y$.” Since $H(X|Y)$ is the conditional entropy (uncertainty about $X$ after knowing $Y$), the difference $H(X) - H(X|Y)$ measures exactly how much information $Y$ gave us about $X$.
By the chain rule of entropy $H(X,Y) = H(X) + H(Y|X) = H(Y) + H(X|Y)$ we can derive:
$$I(X; Y) = H(Y) - H(Y|X)$$Combining both:
$$I(X; Y) = H(X) + H(Y) - H(X,Y)$$Note the following properties:
- Symmetry: $I(X; Y) = I(Y; X)$
- knowing $Y$ tells you as much about $X$ as knowing $X$ tells you about $Y$
- Non-negativity: $I(X; Y) \geq 0 $
- Due to non-negativity of $D_{KL}$
- With equality iff $X$ and $Y$ are independent
- Self-Information: $I(X; X) = H(X)$
- This is why entropy is sometimes called “self-information”—it’s just mutual information of a variable with itself. Note that $P(X,X)=P(X)$.
Here’s the full picture:
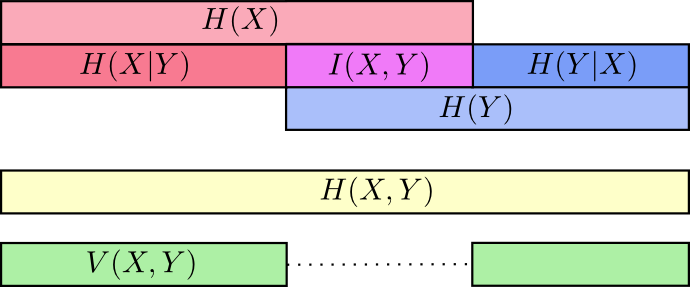
When $X$ and $Y$ are independent, there’s no overlap—$I(X;Y) = 0$. When they’re perfectly correlated, they share all their information—$I(X;Y) = H(X) = H(Y)$.
5 Language Modelling
5.1 Cross-Entropy, Maximum Likelihood Estimation, Multi-class Classification
The cross entropy is often used as an objective/loss function in multi-class classification, when training machine learning (ML) or large language models (LLM). This objective is essentially minimizing the distance between our model’s distribution and the ground truth distribution:
- $P$ = true labels (the ground truth data distribution)
- $Q$ = predicted probabilities (our model’s beliefs)
Minimizing cross-entropy is equivalent to maximum likelihood estimation (MLE)! Given a sample dataset $\{x_1, \ldots, x_n\}$ (sample datapoints not the alphabet here) drawn from true distribution $P$, define the likelihood of data under our model with parameters $\theta$:
$$\mathcal{L}(\theta) = \prod_{i=1}^{n} q_\theta(x_i)$$We seek
$$\hat{\theta} = \arg\max_\theta \mathcal{L}(\theta) = \arg\max_\theta \prod_{i=1}^{n} q_\theta(x_i) $$Convert the product to a sum via logarithms (since logarithms are strictly increasing and do not affect argmax), then normalize by sample count:
$$\hat{\theta} = \arg\max_\theta \frac{1}{n}\sum_{i=1}^{n} \log q_\theta(x_i)$$By the Law of Large Numbers, this sample average converges to an expected value as $n \to \infty$. Specifically, the expectation is with respect to the true underlying distribution $P$:
$$\frac{1}{n}\sum_{i=1}^{n} \log q_\theta(x_i) \to \mathbb{E}_{x \sim P}\left[\log q_\theta(x)\right] = \sum_{i} p(x_i) \log q_\theta(x_i)$$Negate and minimize:
$$\hat{\theta} = \arg\min_\theta \left\{ -\sum_{i} p(x_i) \log q_\theta(x_i) \right\} = \arg\min_\theta H_P(Q_\theta)$$MLE is equivalent to minimizing cross-entropy!
Note that minimizing cross-entropy is also equivalent to minimizing the KL divergence $D_{KL}(P \| Q)$. Since $H(P)$ is the entropy of the true distribution, it’s independent of the model parameters $\theta$.
$$\arg\min_\theta H_P(Q_\theta) = \arg\min_\theta [D_{KL}(P \| Q_\theta) + H(P)] = \arg\min_\theta D_{KL}(P \| Q_\theta)$$MLE in Practice
In practice, we don’t have access to the true distribution $P$. Instead, we can approximate this by using a batch of sample data. Consider a classification batch of $n$ samples, where each sample $i$ has a true label $y_i$ (one-hot: probability 1 for the true class, 0 elsewhere) and the model predicts $q_\theta(y=k)$ for each class $k$. The batch loss is:
$${L}(\theta) = -\frac{1}{n} \sum_{i=1}^{n} \log q_\theta(y_i)$$Note in practice we only sum the model log probabilities for the class corresponding to the true class for each sample, despite having log probs for all classes. Now regroup by class with $n_k$ samples in each class $k$, so we can rewrite the sum as:
$$ {L}(\theta) = -\frac{1}{n} \sum_{k=1}^{K} n_k \log q_\theta(y=k) = -\sum_{k=1}^{K} \frac{n_k}{n} \log q_\theta(y=k)$$Note that $\hat{p}(y=k) = \frac{n_k}{n}$ is the empirical frequency of class $k$ in the batch
$$ {L}(\theta) = -\sum_{k=1}^{K} \hat{p}(y=k) \log q_\theta(y=k) = H_{\hat{P}}(Q_\theta)$$This is exactly the cross-entropy formula! One-hot labels, when averaged over a batch, naturally produce an empirical distribution. With sufficient data, $\hat{p}(y=k) \to p(y=k)$ (the true class distribution), so batch averaging realizes the theoretical MLE objective.
5.2 Auto-regressive Language Modelling
So we’ve seen how cross-entropy applies to multi-class classification. We now extend this to LLMs that generate long sequences of text. Consider a sequence of tokens $X=(x_1, x_2, \dots, x_T)$. The objective of LLMs is to model the joint probability distribution of this sequence $p(x_1, x_2, \dots, x_T)$. We can use the chain rule of probability to factor this joint distribution into a product of conditional probabilities:
$$p(x_1,\ldots,x_T) = p(x_1) \cdot p(x_2 | x_1) \cdot p(x_3 | x_1, x_2) \cdots = \prod_{t=1}^T p(x_t|x_1,\ldots,x_{t-1})$$An autoregressive LLM is just a sequence of simple classification tasks! At each timestep $t$,
- It takes the context $x_{\lt t}$ (e.g., “The quick brown fox…”).
- It predicts a probability distribution $Q_\theta(\cdot | x_{\lt t})$ over the entire vocabulary (e.g., 50,000 possible next tokens). Each token is a class.
- The “true label” $P_t$ is simply the one-hot vector for the token that actually comes next in the training data (e.g., “jumps”).
The total loss for one sequence ${L}_X(\theta)$ is just the sum of the cross-entropy losses across all timesteps:
$${L}_X(\theta) = \sum_{t=1}^T -\log q_\theta(x_t | x_{\lt t}) $$This sum of losses is equivalent to the negative log-likelihood of the entire sequence $X$:
$${L}_X(\theta) = -\sum_{t=1}^T \log q_\theta(x_t | x_{\lt t}) = -\log \left( \prod_{t=1}^T q_\theta(x_t | x_{\lt t}) \right) = -\log q_\theta(X)$$LLMs are just doing MLE on the joint distribution of the entire sequence.
5.3 Information Theory of LLMs
Prediction is essentially compression.
Generalization
Information theory can help us analyze generalization in LLMs, by measuring a model’s capacity in bits [Morris, 2025]. Morris splits learned information into “unintended memorization” (information specific to dataset) and “generalization” (underlying distribution). They then compute the total capacity of LLMs, where models in the GPT family have an approximate capacity of 3.6 bits-per-parameter. When a model is trained on data whose information content exceeds its capacity, it must make a tradeoff between memorizing individual datapoints, or begin extracting general patterns that compress the data more efficiently. This transition point—where unintended memorization gives way to generalization—occurs precisely when the dataset’s entropy exceeds the model’s capacity. This explains phenomena like “grokking” and double descent.
Information in Chain-Of-Thought
When an LLM uses Chain-of-Thought (CoT) to solve a problem, it generates intermediate steps. But are these steps actually useful? Researchers quantify [Ton, 2025] the usefulness of each reasoning step ($X_t$) by measuring its “information gain”—the conditional mutual information it shares with the final correct answer ($Y$), given all the previous steps ($X_{\lt t}$):
$$G_t = I(Y; X_t | X_{ \lt t})$$This metric basically answers: “How much new and relevant information did this step provide about the final answer, given everything the model has already said?”
6 Conclusion
Whether we’re designing optimal codes for data compression, training models to predict the next token, or evaluating multi-step reasoning, we return to the same fundamental question: How much information is really here? As we’ve seen throughout this post, entropy—in all its forms—is often the answer.
References
Entropy, Cross-Entropy, KL Divergence
Zhu, J. Information Theory and Machine Learning. University of Wisconsin-Madison, CS 769 Lecture Notes.
Sarang, N. (2024). Entropy, Cross-Entropy, KL Divergence, and Mutual Information.
James Explains. (2024). Information Theory - Entropy, Cross Entropy, KL Divergence [Video]. YouTube.
Bendersky, E. (2025). Cross-Entropy and KL Divergence. Eli Bendersky’s Website.
Maulik, A. Entropy. Indian Institute of Technology Guwahati, CS Lecture Slides.
Olah, C. (2015). Visual Information Theory.
Goodfellow, I., Bengio, Y., & Courville, A. (2016). Deep Learning (Chapter 3: Probability and Information Theory). MIT Press.
Tan, Z., Li, C., & Huang, W. (2024). The Information of Large Language Model Geometry.
Ton, J.F., Taufiq, M.F., & Liu, Y. (2025). Understanding Chain-of-Thought in LLMs through Information Theory. ICML 2025
Morris, J. X., Sitawarin, C., Guo, C., Kokhlikyan, N., Suh, G. E., Rush, A. M., Chaudhuri, K., & Mahloujifar, S. (2025). How much do language models memorize?.
Source Coding Theorem
Wikipedia. Kraft–McMillan Inequality.
Wikipedia Shannon's Source Coding Theorem.
Bernstein, M. Shannon's Source Coding Theorem. Matthew Bernstein’s Blog.
Singh, A. (2015). Information Theory. Carnegie Mellon University, 10-704 Lecture Notes.
Venkataramanan, R. (2025). 3F7: Information Theory and Coding - Handouts 2 & 3. University of Cambridge, Department of Engineering.
Olah, C. (2015). Visual Information Theory. Chris Olah does an awesome job explaining the intuition behind entropy and its related concepts ↩︎
Technically the equal area math only holds if we work with natural logs instead of base 2 logs as $\int_{x'}^{\infty} 2^{-x} \, dx = \frac{2^{-x'}}{\ln 2}$ We are working with base 2 logs instead of natural logs, but we omit the constant scaling factor in our calculations if not they will look rather messy. ↩︎ ↩︎
I chose not to use Olah’s visual proof exactly here because his proof suggests that we need the benefit/cost ratio to be 1. He suggests any deviation in the allocation of budget will change the ratio to not be 1, which is not exactly the right argument. The important thing is that all symbols have the same benefit/cost ratio, so the allocation of budget is optimum. ↩︎
A true metric must satisfy symmetry: $d(A, B) = d(B, A)$ and the triangle inequality: $d(A, C) \leq d(A, B) + d(B, C)$. KL divergence doesn’t satisfy either property, so it is not really a proper metric for measuring distances between distributions. ↩︎
Some researchers define the Jensen-Shannon divergence as a symmetric alternative: $\text{JS}(P, Q) = \frac{1}{2}D_{KL}(P \| M) + \frac{1}{2}D_{KL}(Q \| M)$ where $M = \frac{P + Q}{2}$. This is a true metric (and $\sqrt{\text{JS}}$ is a metric), but it obscures the directed nature of the problem. For machine learning, forward KL is almost always the right choice. ↩︎